What is Search Engine and how does it work – Google, Bing and Yahoo
What is a search engine? A search engine is an online tool that is designed to search for websites on the internet based on the user’s search query. I...
Read article
The World Wide Web commonly referred to as WWW, W3, or the Web is an interconnected system of public webpages accessible through the Internet. These webpages and documents are interconnected by means of hyperlinks that users click on for information. This information can be in different formats, including text, images, audio and video.
The Web is not the same as the Internet: the Web is one of many applications built on top of the Internet.
The World Wide Web has the following four components namely Hypertext Transfer Protocol (HTTP), Uniform Resource Locator (URL), Hypertext Markup Language (HTML) and Hyperlinks
This protocol is used to transfer hypertexts (special format of the text that can contain links to other texts) over the internet and it is defined by the www (world wide web) for information transfer. This protocol defines how the information needs to be formatted and transmitted and the various actions the web browsers should take in response to the calls made to access a particular web page.
Whenever a user opens their web browser, the user will indirectly use HTTP as this is the protocol that is being used to share text, images, and other multimedia files on the World Wide Web.
HTTP therefore enables users to access web pages by standardizing communications and data transfer between the internet’s servers and clients.
A URL (Uniform Resource Locator) is a unique identifier used to locate a resource on the Internet. Such resources can be an HTML page, a CSS document, an image, etc.
Here is an example of the URL https://developer.mozilla.org
A URL is composed of different parts, some mandatory and others optional. The most important parts are highlighted on the URL diagram below

1. Scheme
The first part of the URL is the scheme, which indicates the protocol that the browser must use to request the resource (a protocol is a set method for exchanging or transferring data around a computer network).
Usually for websites the protocol is HTTPS or HTTP (its unsecured version). Addressing web pages requires one of these two, but browsers also know how to handle other schemes such as mailto: (to open a mail client), so don’t be surprised if you see other protocols.
2. Authority
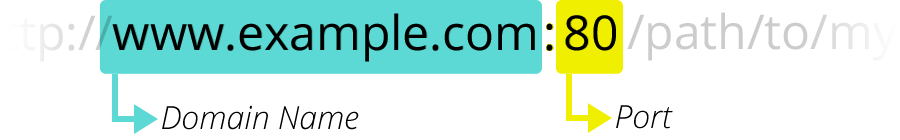
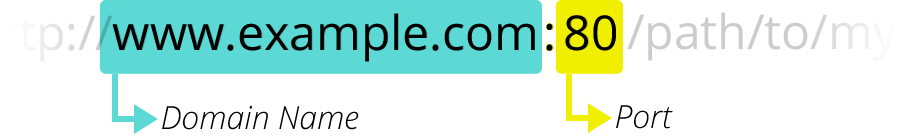
Next follows the authority, which is separated from the scheme by the character pattern ://. If present the authority includes both the domain (e.g. www.example.com) and the port (80), separated by a colon:
The domain indicates which Web server is being requested. Usually this is a domain name, but an IP address may also be used (but this is rare as it is much less convenient).
The port indicates the technical “gate” used to access the resources on the web server. It is usually omitted if the web server uses the standard ports of the HTTP protocol (80 for HTTP and 443 for HTTPS) to grant access to its resources. Otherwise it is mandatory.
3. Path to resource
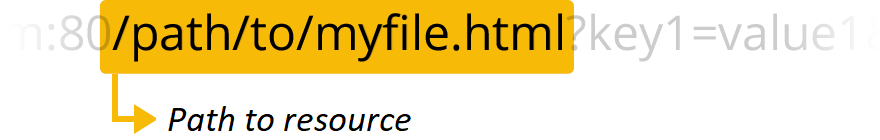
/path/to/myfile.html is the path to the resource on the Web server. In the early days of the Web, a path like this represented a physical file location on the Web server. Nowadays, it is mostly an abstraction handled by Web servers without any physical reality.
4. Parameters
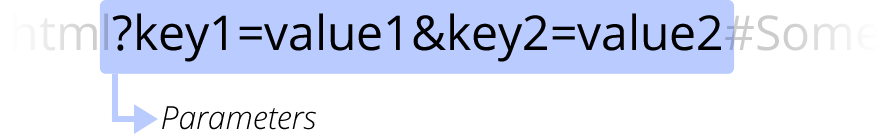
?key1=value1&key2=value2 are extra parameters provided to the Web server. Those parameters are a list of key/value pairs separated with the & symbol. The Web server can use those parameters to do extra stuff before returning the resource.
The HyperText Markup Language or HTML is the standard markup language for documents designed to be displayed in a web browser. It can be assisted by technologies such as Cascading Style Sheets (CSS) and scripting languages such as JavaScript.
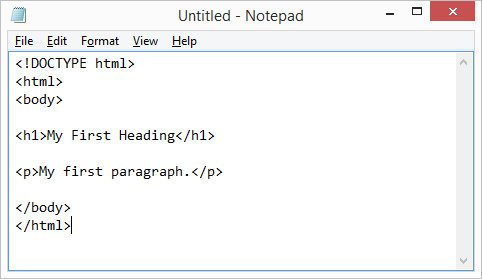
HTML describes the structure of web pages using elements or tags and displays the content of these pages through a web browser.
The diagram below shows a simple structure of HTML document. We will cover more about HTML in the subsequent lessons and share videos in our Youtube Channel. Click here to subscribe
Hyperlink is an electronic link providing direct access from one distinctively marked place in a hypertext or hypermedia document to another in the same or a different document.
This example shows how to create a link to W3Schools.com
<a href=”https://www.w3schools.com/”>Visit W3Schools.com!</a>
Though the World Wide Web is a big part of the Internet, it is not the entire Internet. The World Wide Web (WWW) is just one of many applications built on top of the internet, a vast, global network of multiple smaller networks while the Internet is the entire data communications system that connects the world, including hardware and software.
World Wide Web (WWW) is an enormous system of interlinked hypertext documents that can be accessed with a web browser. It is a communications model or platform that enables the retrieval or exchange of information over the internet through HTTP. Through the WWW, users can access web pages over the internet by following a series of HTTP links.
Both the internet and the web operate within a client-server model. A server is a program that accepts requests from other computers, known as clients, on the network to store and transmit documents. Clients request documents from a server when a user asks for them and then displays them on the user’s screen.
When you enter something like Google.com the request goes to one of many special computers on the Internet known as Domain Name Servers (DNS). All these requests are routed through various routers and switches.
The domain name servers keep tables of machine names and their IP addresses, so when you type in Google.com it gets translated into a number, which identifies the computers that serve the Google Website to you.
When you want to view any page on the Web, you must initiate the activity by requesting a page using your browser. The browser asks a domain name server to translate the domain name you requested into an IP address. The browser then sends a request to that server for the page you want, using a standard called Hypertext Transfer Protocol or HTTP.
The server should constantly be connected to the Internet, ready to serve pages to visitors. When it receives a request, it looks for the requested document and returns it to the Web browser. When a request is made, the server usually logs the client’s IP address, the document requested, and the date and time it was requested. This information varies server to server.
An average Web page actually requires the Web browser to request more than one file from the Web server and not just the HTML page, but also any images, style sheets, and other resources used in the web page. Each of these files including the main page needs a URL to identify each item. Then each item is sent by the Web server to the Web browser and Web browser collects all this information and displays them in the form of Web page.
Summary of how does the web works
What is a search engine? A search engine is an online tool that is designed to search for websites on the internet based on the user’s search query. I...
Read articleIntroduction The Internet is an increasingly important part of everyday life for people around the world and keeps on defining how people co-exists wi...
Read articleWhat is Routing? Routing is the process of moving data across different networks or internetworks between hosts. Information is transmitted according...
Read article
Join the conversation
Leave a comment
Your email address will not be published. Comments are moderated before they appear.