Year-End IT Audit: 10 Things to Review Before 2027
A ten-point year-end technology audit covering security, backups, subscriptions, data protection and planning for the year ahead.
Read article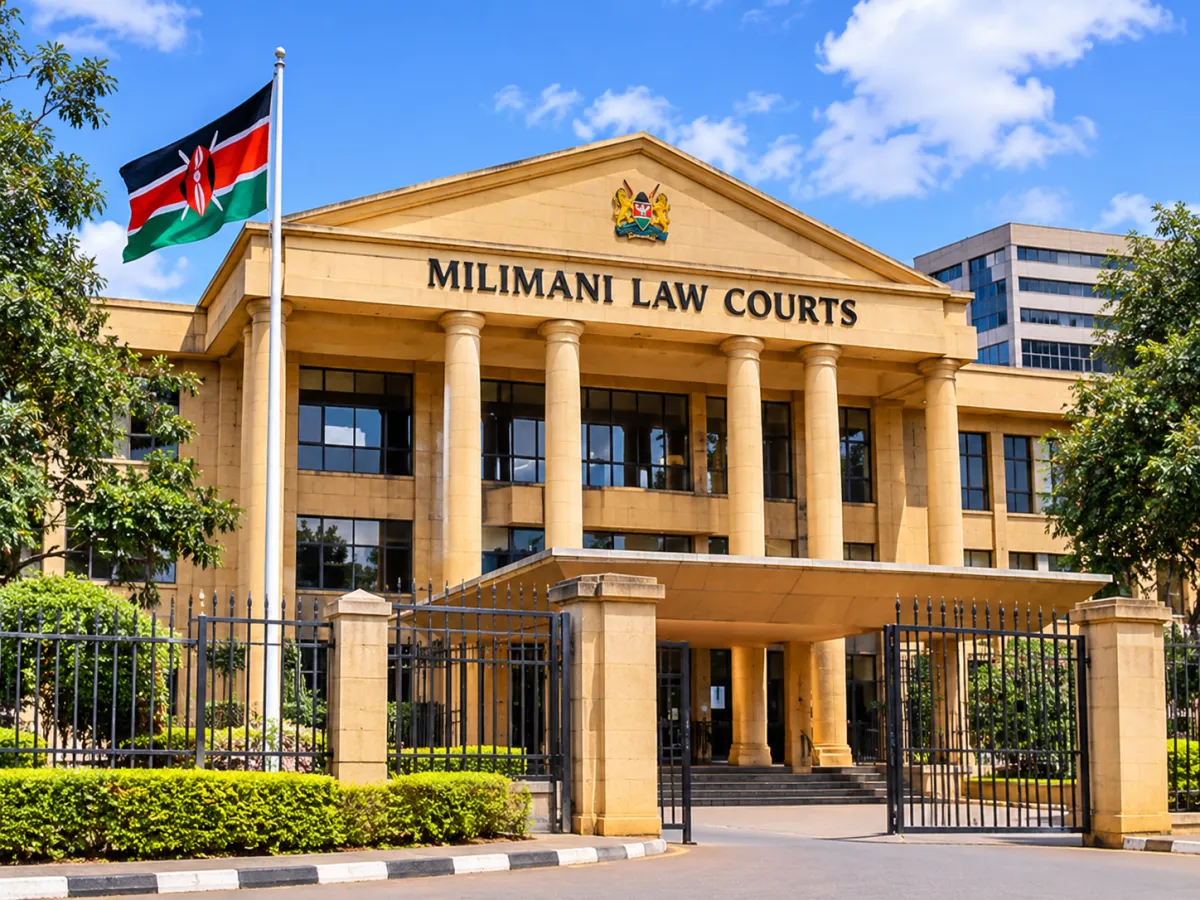
Case backlogs are one of the most persistent challenges facing justice systems around the world. By the time a case is officially recognised as delayed, months or years may already have been lost. Machine learning offers a new tool: estimating early how long a case is likely to take, so that courts can plan and intervene sooner.
Courts hold years of historical records: the type of case, the court, the parties, whether they had legal representation, the number of hearings and adjournments, and how long each case ultimately took. Machine learning models can learn patterns from this history and estimate the likely duration of new cases.
The aim is not to decide cases. It is to support planning: allocating resources, scheduling hearings and flagging cases that are at risk of becoming part of the backlog.
Our JaliHaki project, built on anonymised records from Kenyan magistrate courts, uses three stages:
Each case is then placed in a risk tier, from Low to Critical, so registrars can focus attention where it is most needed.
Patterns like these are what make early prediction useful. In the research behind JaliHaki, the nature and category of a case were the strongest signals at filing time, while the pace of proceedings, such as delays to the first mention and the number of adjournments, became the strongest signals once a case was under way.
Using machine learning in courts demands particular care:
The same approach applies wherever organisations need to anticipate how long processes will take: insurance claims, permit applications, procurement and customer service tickets. If you have historical data and a backlog problem, our machine learning and AI team can assess whether prediction could help.
A ten-point year-end technology audit covering security, backups, subscriptions, data protection and planning for the year ahead.
Read articleEight things to look for in an e-learning platform, from course structure and progress tracking to verifiable certificates and online payments.
Read articleA plain-language comparison of shared, VPS and cloud hosting, with the questions to ask any hosting provider.
Read article
Join the conversation
Leave a comment
Your email address will not be published. Comments are moderated before they appear.